 GeForce RTX 4070 Price, 12GB VRAM & Local LLMs
Price alert
We'll email you when the eBay (US) price reaches your target.
NVIDIA's RTX 4070 (2023) is a midrange gaming card with 12GB of VRAM that runs Gemma 4 12B at 4-bit at about 49 tokens/s. Some cards built since August 2024 use GDDR6 memory instead and generate a little slower.
eBay
GeForce RTX 4070 price history
eBay
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
GeForce RTX 4070 VRAM & full specs
- Memory12 GB · GDDR6X
- Bandwidth504 GB/s
- FP16 / BF16116.8 TFLOPS
- FP8 / INT8233.6 / 233.6 TOPS
- Bus width
- 192-bit
- Architecture
- Ada Lovelace (AD104)
- Cores
- 5,888
- Tensor cores
- 184
- Ecosystem
- CUDA
- Interface
- PCIe 4.0 x16
- NVLink
- Not supported
- Power
- 200 W
- Power connector
- 公版 16-pin 12VHPWR(附转接线);多数非公版 1× 8-pin
- Slots
- 2
- Length
- 244 mm
- Type
- Consumer
- Launch date
- Apr 13, 2023
- MSRP
- $599
Best GeForce RTX 4070 deals
Powered by VRAMGlass real-time price tracking — handpicking the best-value hardware deals across the web
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
 UsedDell Alienware Nvidia RTX 4070 12GB Fan Graphics Card GPU PCTop Rated$665Buy on eBay
 UsedGIGABYTE Windforce OC GeForce RTX 4070 12GB - Graphics Card - ExcellentTop Rated$690Buy on eBay
 UsedZOTAC Twin Edge OC GeForce RTX 4070 12GB - Graphics Card - Excellent ConditionTop Rated$690Buy on eBay
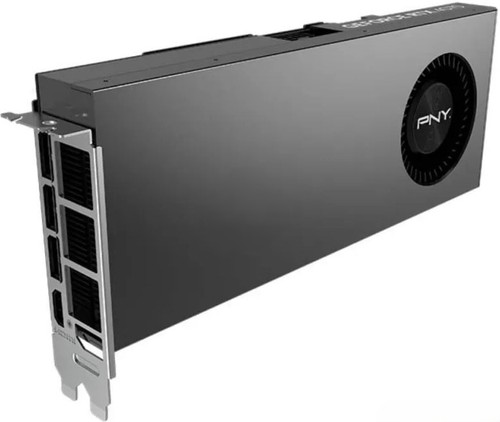 UsedPNY RTX 4070 12GB GDDR6X VERTO DUAL FAN DLSS3 BLOWER EDITION VIDEO Graphics CardTop Rated$699
$1,299-46%Buy on eBay UsedMSI RTX 4070 12GB GDDR6X GAMING SLIM X VIDEO GRAPHICS CARD 16-pin + WARRANTYTop Rated$728
$899-19%Buy on eBay UsedNVIDIA GeForce RTX 4070 12GB GDDR6X Graphics Card PG141C Founders EditionTop Rated$740Buy on eBay

As an Amazon Associate I earn from qualifying purchases. The price you pay stays the same.
 UsedGaming GeForce RTX 4070 Twin Edge OC DLSS 3 12GB GDDR6X 192-bit 21 Gbps PCIE 4.0 Compact Gaming Graphics Card, IceStorm 2.0 Advanced Cooling, Spectra RGB Lighting, ZT-D40700H-10M (Renewed)$700Buy on Amazon
 UsedNVIDIA GeForce RTX 4070 Founder's Edition Graphics Card (Renewed)$800
$850-6%Buy on Amazon UsedDual GeForce® RTX 4070 OC Edition 12GB GDDR6X, IP5X, Auto-Extreme Technology, 144-Hour Validation Program, HDMI 2.1a, DP 1.4a (Renewed)$900Buy on Amazon
What LLMs can a single GeForce RTX 4070 run?
A single RTX 4070 is best with 9B to 12B models at 4-bit, running Gemma 4 12B at about 49 tokens/s. Going bigger, Gemma 4 26B A4B at 2-bit still fits entirely on the card; among dense models only Qwen3.8 27B at 2-bit fits, and its context is tight.
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
 Gemma 4 E4B8B | 3.8 GB | Runs | 87.5 | 128K |
 Qwen3.5 9B9.7B | 4.1 GB | Runs | 81 | 229K |
| Gemma 4 12B12B | 4.7 GB | Runs | 70.6 | 256K |
| Gemma 4 26B A4B25.2B (3.8B active) | 10.5 GB | Runs | 107.8 | 52K |
| Qwen3.6 27B27.8B | 11.8 GB | Too big | — | — |
| Qwen3.8 27B27.8B | 9.8 GB | Runs | 36.4 | 29K |
 GLM 4.7 Flash30B (3B active) | 11.9 GB | Needs RAM offload | 49.1 | 185K |
| Gemma 4 31B30.7B | 11.8 GB | Too big | — | — |
| Qwen3.6 35B A3B36B (3B active) | 12.3 GB | Needs RAM offload | 73 | 256K |
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
| Gemma 4 E4B8B | 5 GB | Runs | 68.8 | 128K |
| Qwen3.5 9B9.7B | 5.7 GB | Runs | 60.6 | 182K |
| Gemma 4 12B12B | 7.1 GB | Runs | 49.1 | 256K |
| Gemma 4 26B A4B25.2B (3.8B active) | 16.9 GB | Needs RAM offload | 35.9 | 256K |
| Qwen3.6 27B27.8B | 16.8 GB | Too big | — | — |
| Qwen3.8 27B27.8B | 16.5 GB | Too big | — | — |
| GLM 4.7 Flash30B (3B active) | 18.3 GB | Needs RAM offload | 35.1 | 180K |
| Gemma 4 31B30.7B | 18.3 GB | Too big | — | — |
| Qwen3.6 35B A3B36B (3B active) | 22.1 GB | Needs RAM offload | 48.3 | 256K |
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
| Gemma 4 E4B8B | 8.2 GB | Runs | 43.8 | 128K |
| Qwen3.5 9B9.7B | 9.5 GB | Runs | 38 | 68K |
| Gemma 4 12B12B | 12.7 GB | Too big | — | — |
| Gemma 4 26B A4B25.2B (3.8B active) | 26.9 GB | Needs RAM offload | 24.2 | 256K |
| Qwen3.6 27B27.8B | 28.6 GB | Too big | — | — |
| Qwen3.8 27B27.8B | 29 GB | Too big | — | — |
| GLM 4.7 Flash30B (3B active) | 31.8 GB | Needs RAM offload | 21.9 | 170K |
| Gemma 4 31B30.7B | 32.6 GB | Too big | — | — |
| Qwen3.6 35B A3B36B (3B active) | 36.9 GB | Needs RAM offload | 32 | 256K |
RunsFits fully in VRAM; speed is estimated from VRAM bandwidth.
Needs RAM offloadMoE only: expert weights sit in system RAM, so speed is estimated from 70 GB/s RAM bandwidth.
Too bigWon’t fit on one card at this quantization, even with RAM offload.
Full calculation rules are on the Methodology page.
Who it suits
Good fit
- Running 9B to 12B models
Qwen3.5 9B at 4-bit runs at about 61 tokens/s with more than 180K of context
- Running 26B-class MoE models at 2-bit
Gemma 4 26B A4B takes only 10.5 GB and runs entirely on the card at about 108 tokens/s with 52K of context
- Upgrading an older PC
The card draws 200W, NVIDIA recommends a 650W power supply for the system, and many partner cards need just one 8-pin power cable
Not a good fit
- You want a 12B at 8-bit
Gemma 4 12B at 8-bit has 12.7 GB of weights, and with context and runtime overhead added it won't fit in 12GB of VRAM
- Running 27B-class dense models
They start at 16.5 GB at 4-bit, and only Qwen3.8 27B at 2-bit fits, with 29K of context at about 36 tokens/s
- You want 30B-class MoE models entirely on the card
Even at 2-bit, Qwen3.6 35B A3B is 12.3 GB, and with context added it won't fit in 12GB of VRAM, so its experts have to go in system RAM; run that way at 2-bit it does about 73 tokens/s
Before you buy
The GDDR6 version generates about 5% slower
Starting in August 2024, NVIDIA added a 4070 with GDDR6 memory. Everything else is unchanged, but bandwidth drops from 504 to 480 GB/s. In games it's only about 1% slower, but when running models, generation speed follows bandwidth, so it's about 5% slower. The memory type is listed on the box and shown in GPU-Z.
Don't mix up the four 4070s
The 4070, 4070 SUPER and 4070 Ti all have 12GB on a 192-bit bus, so they fit the same models; only the 4070 Ti SUPER has 16GB. In listings, “4070S” means the SUPER, not this card. Before ordering, ask the seller for a GPU-Z screenshot and check that the core count is 5888.
The laptop 4070 has only 8GB
The RTX 4070 Laptop GPU has only 8GB of VRAM on a 128-bit bus, so it's far less capable at running models. If you see a “4070 laptop”, don't estimate from the numbers on this page.
Dual-slot Founders Edition fits small cases
NVIDIA makes a Founders Edition: dual-slot and 244 mm long, powered through a 16-pin connector with an adapter in the box. Many partner cards use a single 8-pin connector instead. Sizes vary, so check the specific model.
Compared with similar GPUs
GeForce RTX 4070 vs GeForce RTX 5070, GeForce RTX 3060 12GB, and GeForce RTX 4060 Ti 16GB: price, VRAM, bandwidth, compute and local LLM speed compared.
| Spec | GeForce RTX 4070 | GeForce RTX 5070 | GeForce RTX 3060 12GB | GeForce RTX 4060 Ti 16GB |
|---|---|---|---|---|
| Memory | 12 GB | 12 GBSame | 12 GBSame | 16 GB33% more |
| Bandwidth | 504 GB/s | 672 GB/s33% higher | 360 GB/s29% lower | 288 GB/s43% lower |
| BF16 / FP16 compute | 117 TFLOPS | 124 TFLOPS6% higher | 51 TFLOPS56% lower | 88 TFLOPS24% lower |
| INT8 compute | 234 TOPS | 247 TOPS6% higher | 102 TOPS56% lower | 177 TOPS24% lower |
| Qwen3.8 27B speed (2-bit) | 36.4 t/s | 47.8 t/s31% faster | 26.4 t/s27% slower | 21.3 t/s41% slower |
| Largest dense model (4-bit) | 16B | 16BSame | 16BSame | 23B44% more |
| Power | 200 W | 250 W25% higher | 170 W15% lower | 165 W18% lower |
| Interface | PCIe 4.0 x16 | PCIe 5.0 x16 | PCIe 4.0 x16 | PCIe 4.0 x8 |
| Released | 2023-04 | 2025-03 | 2021-02 | 2023-07 |
| eBay median |
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
 Amazon.jp
 Xianyu