 A100 80GB PCIe Price, VRAM & Local LLMs
Price alert
We'll email you when the eBay (US) price reaches your target.
With 80GB of VRAM, the NVIDIA A100 80GB PCIe (2021) holds gpt-oss 120B on a single card and runs 30B-class models at 8-bit with long context. It has no fan of its own, so it only works in a case that pushes air straight through it.
eBay
A100 80GB PCIe price history
eBay
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
A100 80GB PCIe VRAM & full specs
- Memory80 GB · HBM2e
- Bandwidth1,935 GB/s
- FP16 / BF16312 TFLOPS
- INT8624 TOPS
- Bus width
- 5,120-bit
- Architecture
- Ampere (GA100)
- Cores
- 6,912
- Tensor cores
- 432
- Ecosystem
- CUDA
- Interface
- PCIe 4.0 x16
- NVLink
- 600 GB/s
- Power
- 300 W
- Power connector
- 8-pin EPS
- Slots
- 2
- Length
- 267 mm
- Type
- Data center
- Launch date
- Jun 28, 2021
Best A100 80GB PCIe deals
Powered by VRAMGlass real-time price tracking — handpicking the best-value hardware deals across the web
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
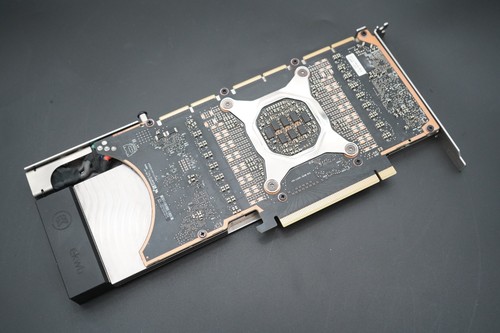 UsedNVIDIA A100 80GB PCIe GPU Accelerator w/EK-Pro Liquid Cooling Water BlockTop Rated$14,100Buy on eBay
 UsedNVIDIA Ampere A100 80GB HBM2e PCIe 4.0 Server Accelerator GPU 900-21001-0020-100$15,999Buy on eBay
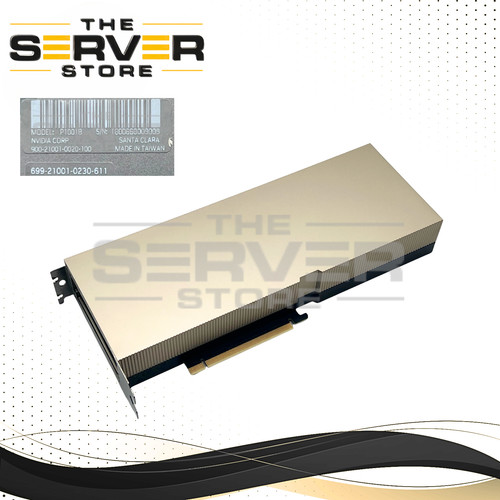 UsedNvidia Ampere A100 80GB HBM2e PCIe 4.0 Server Accelerator GPU 900-21001-0020-100$16,000Buy on eBay
 UsedNvidia Tesla A100 80GB PCIE HBM2e GPU Accelerator Graphics CardTop Rated$18,999Buy on eBay
 UsedNVIDIA 900-21001-0020-000 A100 80GB PCIE GPUTop Rated$18,999Buy on eBay
 UsedNVIDIA 699-21001-0230-600 A100 80GB PCIE GPUTop Rated$18,999Buy on eBay

As an Amazon Associate I earn from qualifying purchases. The price you pay stays the same.

What LLMs can a single A100 80GB PCIe run?
One A100 80GB tops out at gpt-oss 120B at 4-bit; up to 35B, use 8-bit, Qwen3.8 27B at about 47 tokens/s. No FP8 speedup, so in vLLM pick INT4 models.
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
 Gemma 4 26B A4B25.2B (3.8B active) | 10.5 GB | Runs | 169.7 | 256K |
 Qwen3.6 27B27.8B | 11.8 GB | Runs | 104.9 | 256K |
| Qwen3.8 27B27.8B | 9.8 GB | Runs | 122.2 | 256K |
 GLM 4.7 Flash30B (3B active) | 11.9 GB | Runs | 177 | 198K |
| Gemma 4 31B30.7B | 11.8 GB | Runs | 101.5 | 256K |
| Qwen3.6 35B A3B36B (3B active) | 12.3 GB | Runs | 183.6 | 256K |
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
| Gemma 4 26B A4B25.2B (3.8B active) | 16.9 GB | Runs | 152.8 | 256K |
| Qwen3.6 27B27.8B | 16.8 GB | Runs | 77.5 | 256K |
| Qwen3.8 27B27.8B | 16.5 GB | Runs | 78.7 | 256K |
| GLM 4.7 Flash30B (3B active) | 18.3 GB | Runs | 164.5 | 198K |
| Gemma 4 31B30.7B | 18.3 GB | Runs | 70.2 | 256K |
| Qwen3.6 35B A3B36B (3B active) | 22.1 GB | Runs | 166.7 | 256K |
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
| Gemma 4 26B A4B25.2B (3.8B active) | 26.9 GB | Runs | 132.3 | 256K |
| Qwen3.6 27B27.8B | 28.6 GB | Runs | 47.9 | 256K |
| Qwen3.8 27B27.8B | 29 GB | Runs | 47.3 | 256K |
| GLM 4.7 Flash30B (3B active) | 31.8 GB | Runs | 143.1 | 198K |
| Gemma 4 31B30.7B | 32.6 GB | Runs | 41.9 | 256K |
| Qwen3.6 35B A3B36B (3B active) | 36.9 GB | Runs | 146.4 | 256K |
RunsFits fully in VRAM; speed is estimated from VRAM bandwidth.
Needs RAM offloadMoE only: expert weights sit in system RAM, so speed is estimated from 70 GB/s RAM bandwidth.
Too bigWon’t fit on one card at this quantization, even with RAM offload.
Full calculation rules are on the Methodology page.
What LLMs can multiple A100 80GB PCIe cards run?
Two A100 80GB cards (160GB) run Qwen3.8 Flash Next at 4-bit at about 130 tokens/s; DeepSeek V4 Flash takes four. NVLink is supported.
| Model | Size | Cards | Total price | Total VRAM | Speed t/s | Total power |
|---|---|---|---|---|---|---|
| Qwen3.8 Flash Next176B (6B active) | 78.9 GB | 2 cards | $37,998 | 160 GB | 147.5 | 600 W |
 DeepSeek V4 Flash284B (13B active) | 96.8 GB | 2 cards | $37,998 | 160 GB | 129.1 | 600 W |
 Hy3295B (21B active) | 107.2 GB | 2 cards | $37,998 | 160 GB | 74.7 | 600 W |
| GLM 5.3 Flash320B (18B active) | 108.7 GB | 2 cards | $37,998 | 160 GB | 111.8 | 600 W |
| GLM 5.3744B (40B active) | 253.9 GB | 4 cards | $75,996 | 320 GB | 67.2 | 1,200 W |
| Hy4 preview770B (49B active) | 307.2 GBest. | 8 cards | $151,992 | 640 GB | 53 | 2,400 W |
 Muse Spark Open816B (42B active) | 311.2 GB | 8 cards | $151,992 | 640 GB | 61.2 | 2,400 W |
 Kimi K2.7 Code1,000B (32B active) | 339.5 GB | 8 cards | $151,992 | 640 GB | 78.2 | 2,400 W |
| Kimi K2.61,000B (32B active) | 340.5 GB | 8 cards | $151,992 | 640 GB | 78.1 | 2,400 W |
 Mistral Large 41,000B (52B active) | 378.3 GB | 8 cards | $151,992 | 640 GB | 53.3 | 2,400 W |
| Model | Size | Cards | Total price | Total VRAM | Speed t/s | Total power |
|---|---|---|---|---|---|---|
| Qwen3.8 Flash Next176B (6B active) | 111.3 GB | 2 cards | $37,998 | 160 GB | 132.9 | 600 W |
| DeepSeek V4 Flash284B (13B active) | 155.1 GB | 4 cards | $75,996 | 320 GB | 104.7 | 1,200 W |
| Hy3295B (21B active) | 182.2 GB | 4 cards | $75,996 | 320 GB | 58.9 | 1,200 W |
| GLM 5.3 Flash320B (18B active) | 199.7 GB | 4 cards | $75,996 | 320 GB | 80.7 | 1,200 W |
| GLM 5.3744B (40B active) | 467.3 GB | 8 cards | $151,992 | 640 GB | 44.2 | 2,400 W |
| Hy4 preview770B (49B active) | 467.3 GB | 8 cards | $151,992 | 640 GB | 38.9 | 2,400 W |
| Muse Spark Open816B (42B active) | 505.5 GB | 8 cards | $151,992 | 640 GB | 43.3 | 2,400 W |
| DeepSeek V4.1 Flash763B (8 / 16B active) | 510.3 GB | 8 cardsEngram in RAM | $151,992 | 640 GB | 71.7 | 2,400 W |
| Kimi K2.61,000B (32B active) | 583.7 GB | 8 cards | $151,992 | 640 GB | 55.4 | 2,400 W |
| Kimi K2.7 Code1,000B (32B active) | 583.7 GB | 8 cards | $151,992 | 640 GB | 55.4 | 2,400 W |
| Mistral Large 41,000B (52B active) | 604.8 GB | 8 cards | $151,992 | 640 GB | 37.5 | 2,400 W |
| Model | Size | Cards | Total price | Total VRAM | Speed t/s | Total power |
|---|---|---|---|---|---|---|
| DeepSeek V4 Flash284B (13B active) | 161.9 GB | 4 cards | $75,996 | 320 GB | 102.5 | 1,200 W |
| Qwen3.8 Flash Next176B (6B active) | 188.2 GB | 4 cards | $75,996 | 320 GB | 107.6 | 1,200 W |
| Hy3295B (21B active) | 317.7 GB | 8 cards | $151,992 | 640 GB | 42.6 | 2,400 W |
| GLM 5.3 Flash320B (18B active) | 341 GB | 8 cards | $151,992 | 640 GB | 56.3 | 2,400 W |
| Kimi K2.61,000B (32B active) | 594.5 GB | 8 cards | $151,992 | 640 GB | 54.7 | 2,400 W |
| Kimi K2.7 Code1,000B (32B active) | 594.5 GB | 8 cards | $151,992 | 640 GB | 54.7 | 2,400 W |
Rows marked “Engram in RAM” need about 203 GB of extra system RAM. Full calculation rules are on the Methodology page.
Who it suits
Good fit
- Running 70B- to 120B-class models on one card
gpt-oss 120B at 4-bit and Llama 3.3 70B at 8-bit both fit, with no need to split them across cards
- You want 30B-class models at 8-bit with long context
Qwen3.8 27B at 8-bit can use the full 256K, at about 47 tokens/s
- You may add a second card later
Two cards paired with an NVLink bridge give you 160 GB, enough for Qwen3.8 Flash Next at 4-bit
- You need to share it among several people
MIG splits it into two 40GB slices, so each person can run an 8-bit 27B
Not a good fit
- You need speed on long documents or with many concurrent users
It has less than half the H100's compute, and no FP8
- You want to drop it into a regular workstation and go
The card has no fan, so all 300W of heat has to be carried away by case airflow
Before you buy
Tell the factory PCIe version from SXM4 conversions
On the used market, some sellers fit server SXM4 modules onto adapter boards and sell them as PCIe cards. Listing titles often say “SXM4 converted”, and even the sellers admit the firmware still identifies the card as the SXM version. Converted cards work, but cooling, power delivery and stability depend on whoever made the adapter board, and there is no factory warranty. Run nvidia-smi once the card arrives: the factory PCIe version shows “A100 80GB PCIe”, while a converted card shows “A100-SXM4-80GB” (lspci device IDs 20B5 and 20B2 respectively).
All 300W leaves through airflow
The card has no fan, so all 300W of heat has to be carried off by the heatsink and case airflow, 50W more than the 40GB version. In a workstation, either add an air shroud with a high-static-pressure fan or switch to a water block. Power comes in through one 8-pin CPU (EPS) connector, so a regular power supply needs a PCIe-to-CPU 8-pin adapter cable.
Splitting it among users with MIG
MIG splits one card into several mini GPUs that don't interfere with each other, and every slice on the 80GB version is twice the size of the 40GB version's. Splitting all the way to seven slices gives 10GB each, enough for Gemma 4 12B at 4-bit; splitting into two 40GB slices lets each run Qwen3.8 27B at 8-bit (29 GB).
FP8 models run, but no faster
Ampere doesn't support FP8 compute. FP8 models still load in vLLM: the weights are stored in FP8 and converted to FP16/BF16 for computation, so you save VRAM but gain no speed. For throughput, look for INT4 versions such as AWQ or GPTQ; if you have enough VRAM, you can also just use the original BF16 weights.
Compared with similar GPUs
A100 80GB PCIe vs H100 PCIe and RTX PRO 6000: price, VRAM, bandwidth, compute and local LLM speed compared.
| Spec | A100 80GB PCIe | H100 PCIe | RTX PRO 6000 |
|---|---|---|---|
| Memory | 80 GB | 80 GBSame | 96 GB20% more |
| Bandwidth | 1,935 GB/s | 2,000 GB/s3% higher | 1,792 GB/s7% lower |
| BF16 / FP16 compute | 312 TFLOPS | 756 TFLOPS142% higher | 500 TFLOPS60% higher |
| INT8 compute | 624 TOPS | 1,513 TOPS142% higher | 1,000 TOPS60% higher |
| Qwen3.8 27B speed (2-bit) | 122.2 t/s | 125.6 t/sSame | 114.6 t/s6% slower |
| Largest dense model (4-bit) | 136B | 136BSame | 165B21% more |
| Power | 300 W | 350 W17% higher | 600 W100% higher |
| GPU interconnect | NVLink 600 GB/s | NVLink 600 GB/s | Not supported |
| Interface | PCIe 4.0 x16 | PCIe 5.0 x16 | PCIe 5.0 x16 |
| Released | 2021-06 | 2022-03 | 2025-03 |
| eBay median |
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
A100 80GB PCIe rental price per hour
On-demand rental of the A100 80GB PCIe starts at $0.94 per hour (Vast.ai), about $229/month at 8 hours a day. Buying one (eBay median asking price $18,999) pays off in about 14.7 years, 7.3 years or 2.4 years at 4, 8 or 24 hours a day.
| Option | Price | 4 h/day | 8 h/day | 24 h/day | View |
|---|---|---|---|---|---|
 Vast.aiRentUpdated 29 min. ago | $0.94/hr | $114/mo | $229/mo | $686/mo | Rent |
 RunPodRentUpdated 29 min. ago | $1.19/hr | $145/mo | $290/mo | $869/mo | Rent |
 eBayUpdated 3 hr. ago | $18,999 | Payback ~14.7 yrsPower $7/mo | Payback ~7.3 yrsPower $13/mo | Payback ~2.4 yrsPower $39/mo | Buy |
Break-even uses the US residential average ($0.18/kWh) and 300 W rated power, excluding resale value and the rest of the build.
Rental links are referral links: we may receive a commission or credit if you sign up through them. As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
 Amazon.jp
 Xianyu