 GeForce RTX 5060 Price, 8GB VRAM & Local LLMs
Price alert
We'll email you when the eBay (US) price reaches your target.
NVIDIA's RTX 5060 (2025) is an entry-level gaming card with 8GB of VRAM that runs Qwen3.5 9B at 4-bit at about 54 tokens/s, but a 12B at 4-bit won't fit. It comes only in an 8GB version, so a listing that says “5060 16G” is most likely a 5060 Ti.
eBay
GeForce RTX 5060 price history
eBay
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
GeForce RTX 5060 VRAM & full specs
- Memory8 GB · GDDR7
- Bandwidth448 GB/s
- FP16 / BF1676.8 TFLOPS
- FP8 / INT8153.5 / 153.5 TOPS
- Bus width
- 128-bit
- Architecture
- Blackwell (GB206)
- Cores
- 3,840
- Tensor cores
- 120
- Ecosystem
- CUDA
- Interface
- PCIe 5.0 x8
- NVLink
- Not supported
- Power
- 145 W
- Power connector
- 1× 8-pin / 16-pin 12V-2x6
- Type
- Consumer
- Launch date
- May 19, 2025
- MSRP
- $299
Best GeForce RTX 5060 deals
Powered by VRAMGlass real-time price tracking — handpicking the best-value hardware deals across the web
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
 UsedMSI G50608V3C GeForce RTX 5060 8GB Ventus 3X OC Graphics CardTop Rated$440Buy on eBay
 UsedGIGABYTE GeForce RTX 5060 WINDFORCE OC 8G GDDR7 Graphics Card GV-N5060WF2OC-8GDTop Rated$440Buy on eBay
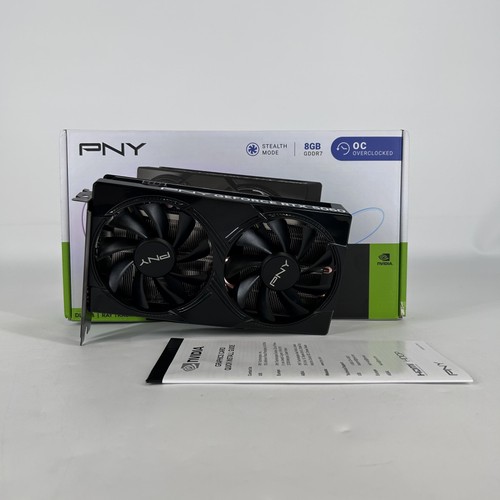 UsedPNY GeForce RTX 5060 8GB RAM - Graphics Card - ExcellentTop Rated$450Buy on eBay
 UsedZotac GeForce RTX 5060 Twin Edge OC 8GB GDDR7 Graphics Card 288-IN780-20076Top Rated$450Buy on eBay
 UsedZotac Gaming GeForce RTX 5060 Twin Edge OC 8GB GDDR7 128BIT Graphics Card$450Buy on eBay
 UsedGIGABYTE GeForce RTX 5060 WINDFORCE OC 8G 8GB GDDR7 Graphics Card GPU$450Buy on eBay

As an Amazon Associate I earn from qualifying purchases. The price you pay stays the same.
 NewASUS Dual NVIDIA GeForce RTX 5060 8GB GDDR7 OC Edition (PCIe 5.0, 8GB GDDR7, DLSS 4, HDMI 2.1b, DisplayPort 2.1b, 2.5-Slot Design, Axial-tech Fan Design, 0dB Technology), 3 Year Warranty$470Buy on Amazon
 NewASUS Dual GeForce RTX 5060 8GB GDDR7 White OC Edition Gaming Graphics Card$510Buy on Amazon
 NewGIGABYTE GeForce RTX 5060 WINDFORCE MAX OC 8G Graphics Card, Cooling System, 8GB 128-bit GDDR7, PCIe 5.0, by NVIDIA, DisplayPort & HDMI - Video Output Interface, GV-N5060WF2MAX OC-8GD Video Card$530Buy on Amazon
What LLMs can a single GeForce RTX 5060 run?
A single RTX 5060 suits models up to 9B, best at 4-bit, where Qwen3.5 9B gets up to 54K of context. A 12B fits only at 2-bit, at about 64 tokens/s; 30B-class MoE models have to keep their experts in system RAM, so speed depends on RAM bandwidth.
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
 Gemma 4 E4B8B | 3.8 GB | Runs | 78.8 | 128K |
 Qwen3.5 9B9.7B | 4.1 GB | Runs | 72.9 | 101K |
| Gemma 4 12B12B | 4.7 GB | Runs | 63.5 | 147K |
| Gemma 4 26B A4B25.2B (3.8B active) | 10.5 GB | Needs RAM offload | 50.8 | 250K |
 GLM 4.7 Flash30B (3B active) | 11.9 GB | Needs RAM offload | 48.6 | 107K |
| Qwen3.6 35B A3B36B (3B active) | 12.3 GB | Needs RAM offload | 71.8 | 256K |
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
| Gemma 4 E4B8B | 5 GB | Runs | 61.8 | 128K |
| Qwen3.5 9B9.7B | 5.7 GB | Runs | 54.4 | 54K |
| Gemma 4 12B12B | 7.1 GB | Too big | — | — |
| Gemma 4 26B A4B25.2B (3.8B active) | 16.9 GB | Needs RAM offload | 35.1 | 221K |
| GLM 4.7 Flash30B (3B active) | 18.3 GB | Needs RAM offload | 34.7 | 102K |
| Qwen3.6 35B A3B36B (3B active) | 22.1 GB | Needs RAM offload | 47.4 | 250K |
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
| Gemma 4 E4B8B | 8.2 GB | Too big | — | — |
| Qwen3.5 9B9.7B | 9.5 GB | Too big | — | — |
| Gemma 4 12B12B | 12.7 GB | Too big | — | — |
| Gemma 4 26B A4B25.2B (3.8B active) | 26.9 GB | Needs RAM offload | 23.7 | 176K |
| GLM 4.7 Flash30B (3B active) | 31.8 GB | Needs RAM offload | 21.7 | 93K |
| Qwen3.6 35B A3B36B (3B active) | 36.9 GB | Needs RAM offload | 31.3 | 212K |
RunsFits fully in VRAM; speed is estimated from VRAM bandwidth.
Needs RAM offloadMoE only: expert weights sit in system RAM, so speed is estimated from 70 GB/s RAM bandwidth.
Too bigWon’t fit on one card at this quantization, even with RAM offload.
Full calculation rules are on the Methodology page.
Who it suits
Good fit
- Small models for everyday chat and translation
Gemma 4 E4B at 4-bit takes only 5 GB, leaving room for the full 128K of context
- You want to get 30B-class MoE models running
Qwen3.6 35B A3B at 2-bit, with its experts in system RAM, runs at about 72 tokens/s, faster than a 12B running entirely on the card
- Small case or older power supply
The card draws 145W, NVIDIA recommends a 550W power supply for the system, and one 8-pin connector is enough
Not a good fit
- You want a 12B at 4-bit
Gemma 4 12B at 4-bit has 7.1 GB of weights, and with context and runtime overhead added it won't fit in 8GB of VRAM
- You want 27B-class dense models
Even Qwen3.8 27B at 2-bit needs 9.8 GB, which an 8GB card can't hold, and putting part of it in system RAM doesn't help either
Before you buy
Almost as fast as the 5060 Ti 8GB for running models
Both cards have 8GB of VRAM and 448 GB/s of bandwidth, and generation speed follows bandwidth, so they're nearly identical. The 5060 has a sixth fewer cores, which only shows when you feed it a long document or a long conversation at once: it processes the prompt a bit slower. For the other card's numbers, see RTX 5060 Ti 8GB.
The laptop 5060 is over 10% slower
The RTX 5060 Laptop GPU also has 8GB, but only 3328 cores and 384 GB/s of bandwidth, so it generates about 14% slower, and its power is held back by the laptop it's built into. If you see a “5060 laptop” or a gaming laptop, don't estimate from the numbers on this page.
Install recent software
The 50 series is recognized only by software built with CUDA 12.8 or later. For llama.cpp and Ollama, just install the latest version; PyTorch has matching prebuilt packages starting with 2.7. If building vLLM yourself or using an old Docker image gives an error that sm_120 is unsupported, your version is too old.
Compared with similar GPUs
GeForce RTX 5060 vs GeForce RTX 5060 Ti 8GB, GeForce RTX 4060, and GeForce RTX 3060 12GB: price, VRAM, bandwidth, compute and local LLM speed compared.
| Spec | GeForce RTX 5060 | GeForce RTX 5060 Ti 8GB | GeForce RTX 4060 | GeForce RTX 3060 12GB |
|---|---|---|---|---|
| Memory | 8 GB | 8 GBSame | 8 GBSame | 12 GB50% more |
| Bandwidth | 448 GB/s | 448 GB/sSame | 272 GB/s39% lower | 360 GB/s20% lower |
| BF16 / FP16 compute | 77 TFLOPS | 95 TFLOPS24% higher | 61 TFLOPS21% lower | 51 TFLOPS34% lower |
| INT8 compute | 154 TOPS | 190 TOPS24% higher | 121 TOPS21% lower | 102 TOPS34% lower |
| Qwen3.8 27B speed (2-bit) | Not supported | Not supported | Not supported | 26.4 t/s |
| Largest dense model (4-bit) | 10B | 10BSame | 10BSame | 16B60% more |
| Power | 145 W | 180 W24% higher | 115 W21% lower | 170 W17% higher |
| Interface | PCIe 5.0 x8 | PCIe 5.0 x8 | PCIe 4.0 x8 | PCIe 4.0 x16 |
| Released | 2025-05 | 2025-04 | 2023-06 | 2021-02 |
| eBay median |
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
 Amazon.jp
 Xianyu