 Tesla V100 32GB Price & Used Prices: Which Local LLMs Can It Run?
Price alert
We'll email you when the eBay (US) price reaches your target.
The Tesla V100 32GB is NVIDIA's 2018 data center card, still running Qwen3.6 35B A3B at 4-bit at about 134 tokens/s. New CUDA and vLLM dropped it.
eBay
Tesla V100 32GB price history
eBay
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
Full Tesla V100 32GB specifications
- Memory32 GB · HBM2
- Bandwidth900 GB/s
- FP16 / BF16112 TFLOPS
- INT856.1 TOPS
- Bus width
- 4,096-bit
- Architecture
- Volta (GV100)
- Cores
- 5,120
- Tensor cores
- 640
- Ecosystem
- CUDA
- Interface
- PCIe 3.0 x16
- NVLink
- Not supported
- Power
- 250 W
- Power connector
- 8-pin CPU (EPS-12V)
- Slots
- 2
- Length
- 267 mm
- Type
- Data center
- Launch date
- Mar 27, 2018
Best Tesla V100 32GB deals on eBay
Hand-picked deals from trusted eBay sellers. Shop with confidence.
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
 UsedP05913-001 /P05470-001 HPE NVIDIA Tesla V100 PCIe 32GB Q9U36A W/Mounting Bracket$705Buy on eBay
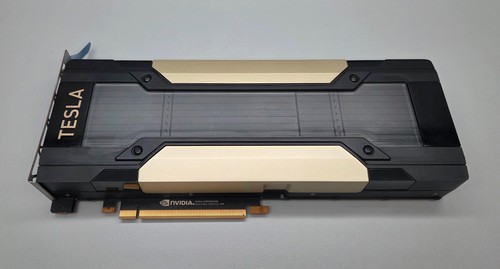 UsedHPE NVIDIA Tesla V100 32GB HBM2 GPU Accelerator (8-pin, 250W) - Q9U36ATop Rated$750Buy on eBay
 UsedDell T39XP NVIDIA Tesla V100 Volta GPU Accelerator 32GB Graphics Card w/Bracket$750Buy on eBay
 UsedNVIDIA Tesla V100 PCIe 32GB Graphics Card GPU 699-2G500-0202-400$750+ shippingBuy on eBay
 UsedNVIDIA/HP Tesla V100 PG500-216 32GB HBM2 Data Center AI HPC Graphics CardTop Rated$809Buy on eBay
 UsedNVIDIA Tesla V100 32GB HBM2 PCIe Dell T39XP, DCGM Pass, Full Test Output in pics$849Buy on eBay
What LLMs can a single Tesla V100 32GB run?
A single V100 32GB fits up to 35B at 4-bit, all with over 160K of context. At 8-bit only 27B-class fits, at about 23 tokens/s.
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
 Gemma 4 E4B8B | 3.8 GB | Runs | 142.5 | 128K |
 Qwen3.5 9B9.7B | 4.1 GB | Runs | 132.7 | 256K |
| Gemma 4 12B12B | 4.7 GB | Runs | 117 | 256K |
| Gemma 4 26B A4B25.2B (3.8B active) | 10.5 GB | Runs | 137.7 | 256K |
| Qwen3.6 27B27.8B | 11.8 GB | Runs | 53 | 256K |
| Qwen3.8 27B27.8B | 9.8 GB | Runs | 62.6 | 256K |
 GLM 4.7 Flash30B (3B active) | 11.9 GB | Runs | 148.4 | 198K |
| Gemma 4 31B30.7B | 11.8 GB | Runs | 51.1 | 246K |
| Qwen3.6 35B A3B36B (3B active) | 12.3 GB | Runs | 158.6 | 256K |
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
| Gemma 4 E4B8B | 5 GB | Runs | 114.2 | 128K |
| Qwen3.5 9B9.7B | 5.7 GB | Runs | 101.5 | 256K |
| Gemma 4 12B12B | 7.1 GB | Runs | 83.2 | 256K |
| Gemma 4 26B A4B25.2B (3.8B active) | 16.9 GB | Runs | 115.5 | 256K |
| Qwen3.6 27B27.8B | 16.8 GB | Runs | 38.3 | 245K |
| Qwen3.8 27B27.8B | 16.5 GB | Runs | 38.9 | 250K |
| GLM 4.7 Flash30B (3B active) | 18.3 GB | Runs | 130.4 | 198K |
| Gemma 4 31B30.7B | 18.3 GB | Runs | 34.5 | 168K |
| Qwen3.6 35B A3B36B (3B active) | 22.1 GB | Runs | 133.5 | 256K |
| Model | Size | Runs? | Speed t/s | Max context |
|---|---|---|---|---|
| Gemma 4 E4B8B | 8.2 GB | Runs | 74.6 | 128K |
| Qwen3.5 9B9.7B | 9.5 GB | Runs | 65.1 | 256K |
| Gemma 4 12B12B | 12.7 GB | Runs | 49.6 | 256K |
| Gemma 4 26B A4B25.2B (3.8B active) | 26.9 GB | Runs | 92.2 | 256K |
| Qwen3.6 27B27.8B | 28.6 GB | Runs | 23.1 | 69K |
| Qwen3.8 27B27.8B | 29 GB | Runs | 22.8 | 63K |
| GLM 4.7 Flash30B (3B active) | 31.8 GB | Runs | 103.9 | 26K |
| Gemma 4 31B30.7B | 32.6 GB | Too big | — | — |
| Qwen3.6 35B A3B36B (3B active) | 36.9 GB | Needs RAM offload | 34.6 | 256K |
RunsFits fully in VRAM; speed is estimated from VRAM bandwidth.
Needs RAM offloadMoE only: expert weights sit in system RAM, so speed is estimated from 70 GB/s RAM bandwidth.
Too bigWon’t fit on one card at this quantization, even with RAM offload.
Full calculation rules are on the Methodology page.
What LLMs can multiple Tesla V100 32GB cards run?
Two V100 32GB cards (64GB) run Llama 3.3 70B at 4-bit at about 14 tokens/s; large MoE needs four. llama.cpp can pool memory too, but slower.
| Model | Size | Cards | Total price | Total VRAM | Speed t/s | Total power |
|---|---|---|---|---|---|---|
| Qwen3.8 Flash Next176B (6B active) | 78.9 GB | 4 cards | $3,580 | 128 GB | 109.1 | 1,000 W |
 DeepSeek V4 Flash284B (13B active) | 96.8 GB | 4 cards | $3,580 | 128 GB | 88.9 | 1,000 W |
 Hy3295B (21B active) | 107.2 GB | 4 cards | $3,580 | 128 GB | 42.8 | 1,000 W |
| GLM 5.3 Flash320B (18B active) | 108.7 GB | 4 cards | $3,580 | 128 GB | 72.3 | 1,000 W |
| Model | Size | Cards | Total price | Total VRAM | Speed t/s | Total power |
|---|---|---|---|---|---|---|
| Qwen3.8 Flash Next176B (6B active) | 111.3 GB | 4 cards | $3,580 | 128 GB | 92.8 | 1,000 W |
| DeepSeek V4 Flash284B (13B active) | 155.1 GB | 8 cards | $7,160 | 256 GB | 66.1 | 2,000 W |
| Hy3295B (21B active) | 182.2 GB | 8 cards | $7,160 | 256 GB | 32.1 | 2,000 W |
| GLM 5.3 Flash320B (18B active) | 199.7 GB | 8 cards | $7,160 | 256 GB | 47.1 | 2,000 W |
| Model | Size | Cards | Total price | Total VRAM | Speed t/s | Total power |
|---|---|---|---|---|---|---|
| DeepSeek V4 Flash284B (13B active) | 161.9 GB | 8 cards | $7,160 | 256 GB | 64.2 | 2,000 W |
| Qwen3.8 Flash Next176B (6B active) | 188.2 GB | 8 cards | $7,160 | 256 GB | 68.6 | 2,000 W |
Full calculation rules are on the Methodology page.
Who it suits
Good fit
- 27B to 31B dense models
About 35 to 39 tokens/s at 4-bit, close to an RTX 3090, with 168K to 250K of context
- MoE models like Qwen3.6 35B A3B
About 134 tokens/s, with room for the full 256K of context
- Putting together 128GB at around 1,000W
Four cards are enough, and they hold Qwen3.8 Flash Next at 4-bit
Not a good fit
- Running 31B models at 8-bit
Gemma 4 31B needs 32.6 GB at 8-bit and doesn't fit
- Relying on recent vLLM
vLLM dropped support for this generation starting with version 0.20 (late April 2026), and FlashAttention 2 doesn't support it either
- Putting it in a regular case
It has no fan and relies on server fans; at 87°C the GPU halves its clocks
Before you buy
PCIe version or SXM2 on an adapter
The 32GB version also comes as either a factory PCIe card or an SXM2 server module. An SXM2 module needs a third-party adapter board to fit an ordinary motherboard, adapter quality varies, and you should plan for 300W. The factory PCIe version draws 250W through one CPU 8-pin connector, which can take two PCIe 8-pin cables through an adapter. When the card arrives, check nvidia-smi: the PCIe version shows “Tesla V100-PCIE-32GB”, and an adapted module shows “Tesla V100-SXM2-32GB”.
How llama.cpp runs on the V100
On the V100, llama.cpp processes long prompts in FP16 by default, drawing its speed from the card's 112 TFLOPS of FP16 compute, though it uses some extra VRAM. When VRAM is tight, you can enable GGML_CUDA_FORCE_MMQ at compile time to save VRAM, with the trade-off that large batches get somewhat slower. When downloading prebuilt packages, pick the CUDA 12 build; the CUDA 13 build no longer supports this card.
Enable Above 4G Decoding on the motherboard
The 32GB version needs 32 GB of address space (16 GB for the 16GB version), and older motherboards won't detect the card without Above 4G Decoding enabled, so check whether your BIOS has this option before installing.
Drivers stop at 580
NVIDIA's 580 is the last driver branch that supports this generation, and from here it gets only maintenance updates. Ollama still officially supports the card and requires a 550 or later driver, so for Ollama, install a driver between 550 and 580.
Compared with similar GPUs
Tesla V100 32GB vs GeForce RTX 3090, Instinct MI50 32GB, and GeForce RTX 2080 Ti 22GB: price, VRAM, bandwidth, compute and local LLM speed compared.
| Spec | Tesla V100 32GB | GeForce RTX 3090 | Instinct MI50 32GB | GeForce RTX 2080 Ti 22GB |
|---|---|---|---|---|
| Memory | 32 GB | 24 GB25% less | 32 GBSame | 22 GB31% less |
| Bandwidth | 900 GB/s | 936 GB/s4% higher | 1,024 GB/s14% higher | 616 GB/s32% lower |
| BF16 / FP16 compute | 112 TFLOPS | 142 TFLOPS27% higher | 27 TFLOPS76% lower | 108 TFLOPS4% lower |
| INT8 compute | 56 TOPS | 285 TOPS407% higher | 53 TOPS6% lower | 215 TOPS284% higher |
| Qwen3.8 27B speed (2-bit) | 62.6 t/s | 64.8 t/s4% faster | 70.3 t/s12% faster | 44 t/s30% slower |
| Largest dense model (4-bit) | 51B | 37B27% less | 51BSame | 34B33% less |
| Power | 250 W | 350 W40% higher | 300 W20% higher | 250 WSame |
| GPU interconnect | Not supported | NVLink 112.5 GB/s | — | NVLink 100 GB/s |
| Interface | PCIe 3.0 x16 | PCIe 4.0 x16 | PCIe 4.0 x16 | PCIe 3.0 x16 |
| Released | 2018-03 | 2020-09 | 2018-11 | 2018-09 |
| eBay median |
As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
Tesla V100 32GB rental price per hour
On Vast.ai, the Tesla V100 32GB rents for $0.17 per hour on demand, about $41/month at 8 hours a day. Buying one (eBay median $895) pays off in about 4.9 years, 2.5 years or 10 months at 4, 8 or 24 hours a day.
| Option | Price | 4 h/day | 8 h/day | 24 h/day | View |
|---|---|---|---|---|---|
 Vast.aiRentUpdated 49 min. ago | $0.17/hr | $21/mo | $41/mo | $123/mo | Rent |
 eBayUpdated 6 hr. ago | $895 | Payback ~4.9 yrsPower $5/mo | Payback ~2.5 yrsPower $11/mo | Payback ~10 moPower $33/mo | Buy |
Break-even uses the US residential average ($0.18/kWh) and 250 W rated power, excluding resale value and the rest of the build.
Rental links are referral links: we may receive a commission or credit if you sign up through them. As an eBay Partner, VRAMGlass may be compensated if you buy through the eBay links on this page. The price you pay stays the same.
 Amazon.jp
 Xianyu